

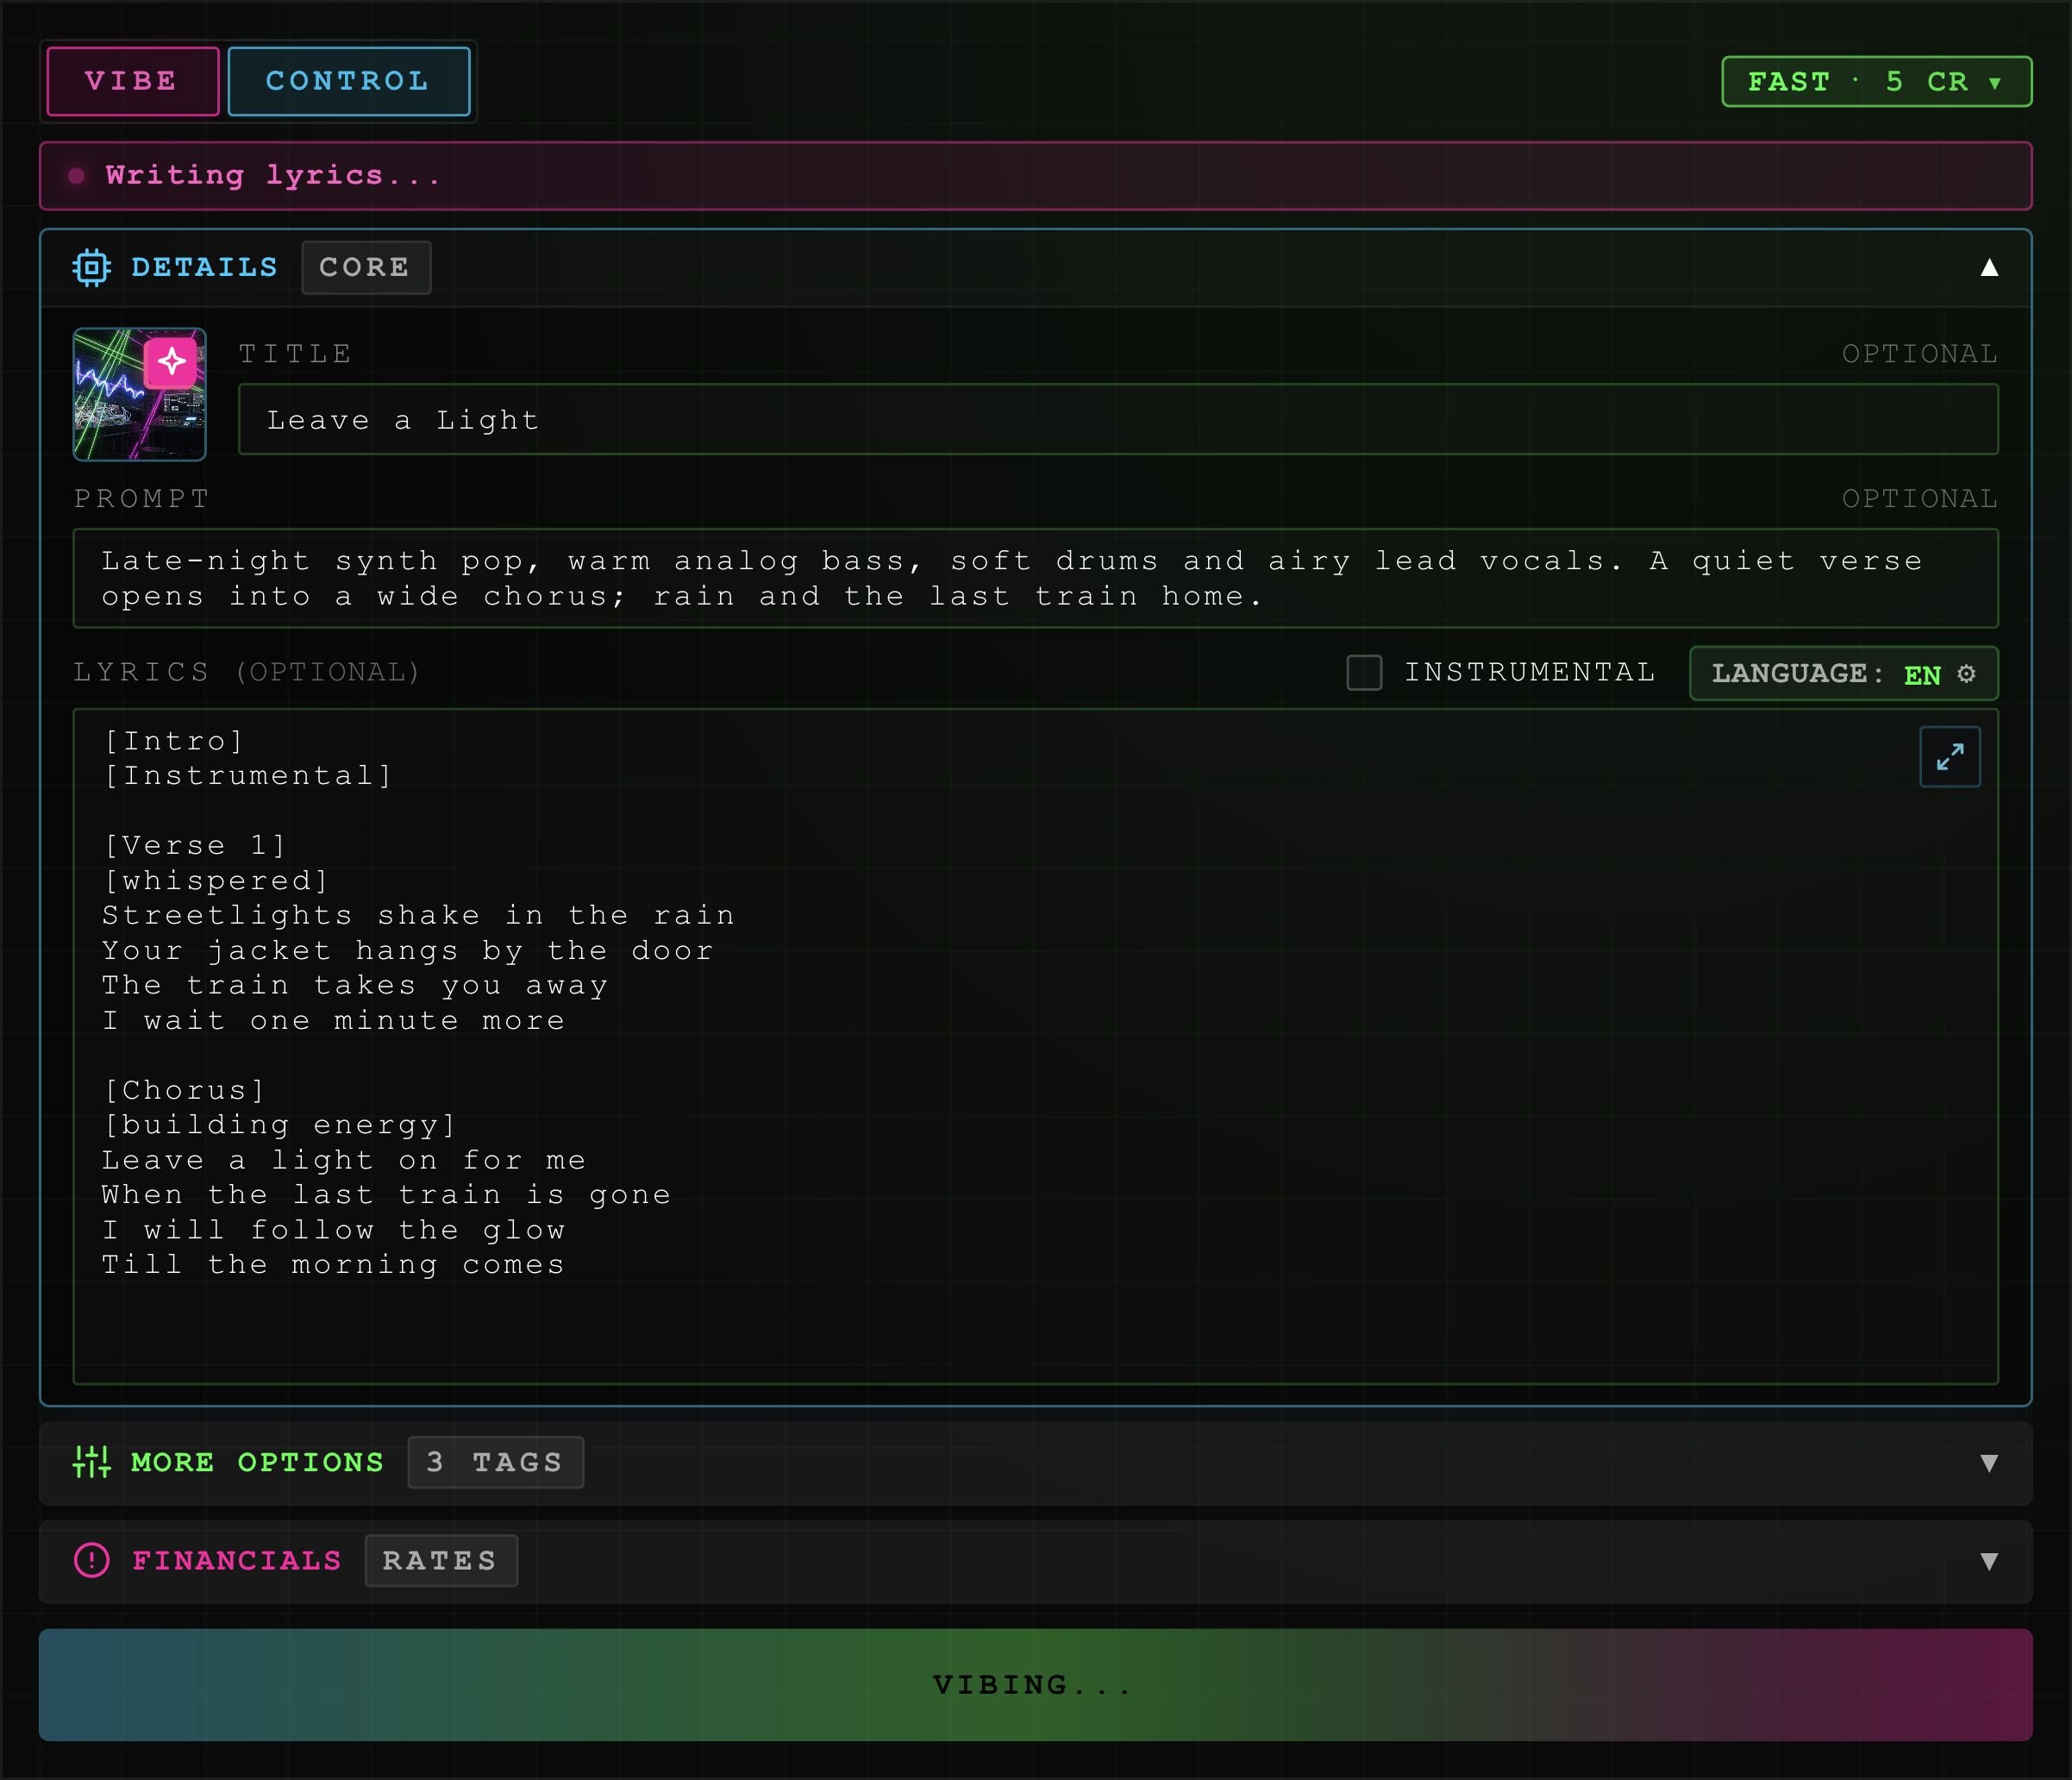
Songwriter fills the current Studio form as fields and lyrics arrive.
Combine the inputs
Text supplies your request directly. Nemotron’s vision model turns an image into a musical brief. Audio supplies transcribed words and signal features. Image and audio preparation run in parallel when you provide both. For audio, Rawchunks prepares mono WAV and measures pitch with YIN, tonal profiles, onset autocorrelation, groove, dynamics and texture. Cartesia transcribes first; ElevenLabs provides the fallback. A lexical filter removes hum, scat and event labels from the spoken brief. A recording can still guide the music through its signal features when it contains no words. Studio records up to 30 seconds. The Vibe walkthrough shows how to combine inputs.Read musical libraries and fill fields
Nemotron-3-Ultra uses three compact libraries: styles, parameters and Lyrics Canvas tags. Tool calls read the relevant library and stream setters for the Studio fields. Planning allows two turns with a 1,024-token budget per turn and temperature 0.6. Vocal drafts then use a separate lyric stream with a 1,200-token budget and temperature 0.75. Structural and performance tags stay in English while lyrics follow the vocal language. Instrumental drafts skip vocal lyric writing.Return the draft early
Nebius Token Factory serves planning, lyrics and vision with streaming enabled and thinking disabled. Field updates reach Studio as tool calls finish; lyric deltas arrive as text. Vision uses a short 180-token output budget and temperature 0.4. Artwork starts alongside the lyric stage.songwriter_ready releases the musical draft before artwork finishes; done closes the full run after the cover result. This overlap keeps artwork off the critical path for reviewing and generating the song.
Use the Songwriter integration for the event contract. Models lists the exact model IDs.